Recorded 29 September 2026 · 21 min
Kyle Jong, a growth engineer at Browserbase, argues that computer-use agents improved not because they learned to see screens more precisely, but because they stopped clicking pixels and started writing code. The shift from coordinate-based clicks to Playwright-style scripts over a page's accessibility tree made agents faster and more repeatable. It also underpins Browserbase's bet that the browser is a universal API for sites that offer none.
The harder problem, Jong says, is no longer capability but permission. Sites such as Amazon resist agents, bots already account for a large share of traffic, and no settled standard exists for proving that an agent is trustworthy. The conversation sits between a technical success story and an unresolved question of identity and access.
Code replaces coordinates — ▶ 1:12
Early computer-use systems, including Anthropic's first version and OpenAI's Operator, took a screenshot and returned pixel coordinates for each click. Jong says this worked in demos but was slow and inaccurate. Models trained for one viewport size, such as the 1288 by 711 he cites, miss clicks when the environment differs. Newer models instead write code in frameworks like Playwright, which they handle well because coding is verifiable. Jong says this is faster and more repeatable, and repeated actions are saved so code need not be regenerated.
Snapshots beat screenshots — ▶ 3:43
A screenshot captures pixels. A snapshot captures the page's accessibility tree, the structure built for visually impaired users, which drops CSS and styling. It gives the model a representation of what is on the page and which actions are possible, which Jong calls more helpful context. He does not argue for abandoning vision: a question like what color something is may still need the image. He favors a hybrid, with models able to choose, and trees pruned so they do not bloat the context window.
Fewer turns, less bloat — ▶ 6:20
Screenshot-per-step loops fill the context window, and Jong says models perform worse as context fills. Reasoning over every step is slow when the model is unsure what to do. Newer models, which Jong says were trained on a lot of compute (he does not know how much), finish tasks in fewer turns. They can also batch predictable actions, returning several clicks as one block of code instead of taking a new screenshot after each. Speed comes from fewer model round trips, not faster individual steps.
Benchmarks are saturating — ▶ 8:29
Industry benchmarks for computer use, including OS World, Online Mind2Web and WebVoyager, are saturating, according to Jong. Browserbase's internal evaluations struggle to produce tasks hard enough to make models fail, and he says every model is around 90% on the benchmarks. Competition therefore shifts to cost and speed, with some models matching others' intelligence in certain domains at half the price. Jong also says models now generalize to new websites well. That claim rests on his internal evaluations, which are not shown.
Browser as universal API — ▶ 10:05
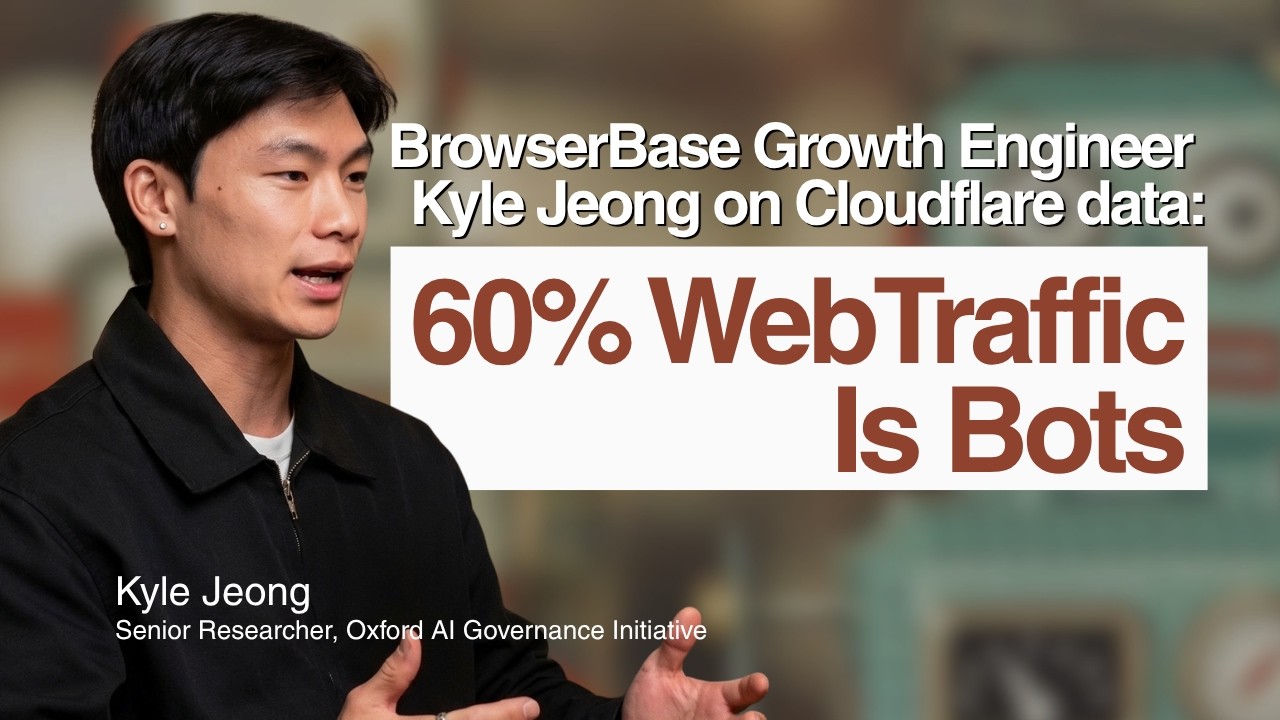
Jong frames the web as built for humans, now carrying 60% bot traffic by Cloudflare's figures. Rebuilding it for agents is possible, and some companies are trying, but he calls it less logical than building infrastructure that lets agents use the web as it exists. His analogy is Waymo and Tesla versus rebuilding roads for self-driving: build a capable vehicle with tight guardrails, noting Waymos cannot yet go on freeways. Browserbase's thesis is that every site should be agent-ready, even a 1990s one.
Agent identity remains unsettled — ▶ 11:39
Jong sees the key gap as trust: sites like Amazon do not want agents such as Meta's Muse (as transcribed) buying on their platforms, and Cloudflare exists to stop unwanted bots. Browserbase's response is to verify its customers through KYB checks, then sign its browser traffic under Cloudflare's Web Bot Auth protocol. He says agent identity is very early. Competing ideas include whether agents get phone numbers or credit cards, and secure authentication for tasks like booking flights is also unsolved.
WebMCP still leaves gaps — ▶ 16:06
Browserbase favors WebMCP and says its agents prioritize a site's native tools when they exist. Working with Stripe, agents can call tools like selecting a payment method at checkout instead of using computer-use workarounds. Jong still expects edge cases that tool sets do not expose. His example is an agent managing a Robinhood account that must read month-over-month performance when only trading is exposed. For site owners he recommends WebMCP, APIs, llms.txt and OAuth-style MCP servers, though Browserbase aims to handle sites that never do.
The core of Jong's argument is that computer use improved by changing the interface between model and machine, not by sharpening the model's eyesight. The first generation, including Anthropic's initial version and OpenAI's Operator, looked at a screenshot and returned the pixel coordinates of a click. Jong says that approach demoed well but was slow and inaccurate. Models trained on one viewport size, such as the 1288 by 711 he mentions, would miss clicks in any differently sized environment. The failure was structural: the agent was being asked to act in the one medium, a rendered screen, that humans had optimized for themselves.
The fix was to let models do what they already do well. Coding is verifiable, Jong notes, so models improved at it quickly, and frameworks like Playwright are familiar territory. An agent that writes code to click a button no longer needs exact coordinates. It also produces something reusable: Jong says the system he discusses saves actions that might repeat, so code need not be regenerated. The speed gain compounds, because a model can batch several predictable clicks into one block of code instead of taking a fresh screenshot after each. Fewer turns also keep the context window from filling, which Jong says degrades performance.
The input changed too. Instead of relying on pixels alone, the agent can read an accessibility tree, a structure built for visually impaired users that strips styling and lists what is on the page and what can be done with it. Editorially, this suggests the web already contained a machine-readable layer, built for another purpose and waiting to be used. Jong stops short of declaring vision obsolete. He expects a hybrid, since some questions, like color, may need the image, and he notes that trees must be pruned to avoid bloating context.
How far these gains generalize is harder to say. Jong reports that standard benchmarks such as OS World, Online Mind2Web and WebVoyager are saturating, with models around 90%, and that Browserbase struggles to write evaluations hard enough to make models fail. He draws the conclusion that models generalize across websites and that competition moves to cost and speed. But the host's sharper test, whether an agent can quickly learn an unfamiliar program, goes unanswered, and the evidence offered is internal and undisclosed. Saturated benchmarks show the tests are easy now, not that the underlying problem is solved.
Browserbase's commercial thesis follows from this. Jong argues the web was built for humans yet already carries 60% bot traffic, citing Cloudflare. In his Waymo-and-Tesla analogy, rebuilding the roads for agents is the less logical path, so Browserbase builds the vehicle and the guardrails. He says every site should be agent-ready through Browserbase, even a 1990s one. That is a vendor's framing, and the analogy contains its own caveat: Jong says Waymos cannot yet go on freeways, so the guardrails are not optional.
Those guardrails are where the discussion turns from capability to permission. Jong points to Amazon resisting Meta's Muse (as transcribed) while Muse works with Shopify and Instacart, and to Cloudflare's reason for existing. Sites do not want unbounded bot access, and some want graduated access, as a Substack writer might choose whether labs can crawl articles. Browserbase's answer is to verify its customers through KYB checks, sign its browser traffic, and work with Cloudflare on Web Bot Auth. Jong is candid that this is early. Whether an agent needs a phone number, a credit card or stored credentials is still open, and so is secure login for tasks like booking a flight.
WebMCP adds another wrinkle. Where a site exposes native tools, as Stripe is doing at checkout, Browserbase's agents will use them rather than computer-use workarounds. Jong still expects edge cases that tool sets omit, such as reading Robinhood performance when only trading is exposed, and says browser agents will cover them. There is an editorial tension here. The more sites publish structured tools and agent-readiness signals, the less the browser fallback is needed. The more sites restrict access, the more that fallback depends on being verified. Jong does not say who ends up deciding which agents get in.
The open question. Who decides which agents count as legitimate, and can verification scale beyond vetted vendors? Browserbase's approach has it verify its customers through KYB checks and sign its browser traffic so Cloudflare can vouch for it. That vouches for a platform, not for an individual agent acting on one person's specific goal. Jong concedes that agent identity is very early, with competing ideas about phone numbers, credit cards and credentials. Without a broadly accepted arbiter, access may depend on bilateral deals between agent providers and gatekeepers.
Watch the full video at https://www.youtube.com/watch?v=okl03z8Wj3g.
Comments ()